
Agentic coding is changing at speeds unprecedented even by the standards of the tech world. The tutorials and resources that are available online mostly cover individual features on simple greenfield scenarios.
During building Bob and while interacting with countless practitioners in the field from a wide range of industries, a set of concepts emerged that help improving the effectiveness and the experience of using Bob.
Those concepts also apply to complex projects using non-mainstream technologies.
Concept 1: The cycle — explore, plan, implement, verify

The most common failure mode in agentic Software Engineering is an absence of structure. Conversational coherence impersonates structure and we are tempted to fold all steps of an implementation into one chat conversation. The sessions feel productive, but the cost only becomes visible in review.
Writing code by hand imposed a structure of its own. Implementation was expensive, so planning before implementing felt intuitively reasonable. Understanding accumulated while you typed, and wrong assumptions were likely to surface during that process. AI Agents remove that friction. Code is cheap now and that also removed our intuition for structure. Structure that was once a by-product of slowness now has to be deliberate.
Using this cycle deliberately can provide the structure:
- Explore produces understanding
- Plan produces decisions
- Implement produces code
- Verify produces evidence.
Following this cycle helps you stay focused, structured, and achieve your goals faster and more consistently.
A single pass through the cycle can take twenty minutes or three days. A pass can contain sub-cycles, and how the time divides between the phases varies widely with the task.
A detailed walk-through of the cycle can be found below in Deep Dive: Run the Cycle.
Concept 2: The context window is the scarce resource
Being deliberate about the context window is the highest-return habit.
What is the context window?
Models are stateless. A chat is not a running session with a memory: each turn resends every previous message and appends the new answer to the end. The context window is the maximum amount of input a model can accept in one of those turns. In Bob V2 that is 270k tokens (context window management).
The window is filling before the first message:
- Loaded up front: Bob's system prompt, the description of the active mode, the repo's
agents.md, and a description of every connected Model Context Protocol (MCP) tool (MCP in Bob). - Added during the session, invisibly: file reads, tool results, skill files Bob pulls in, subagent output.
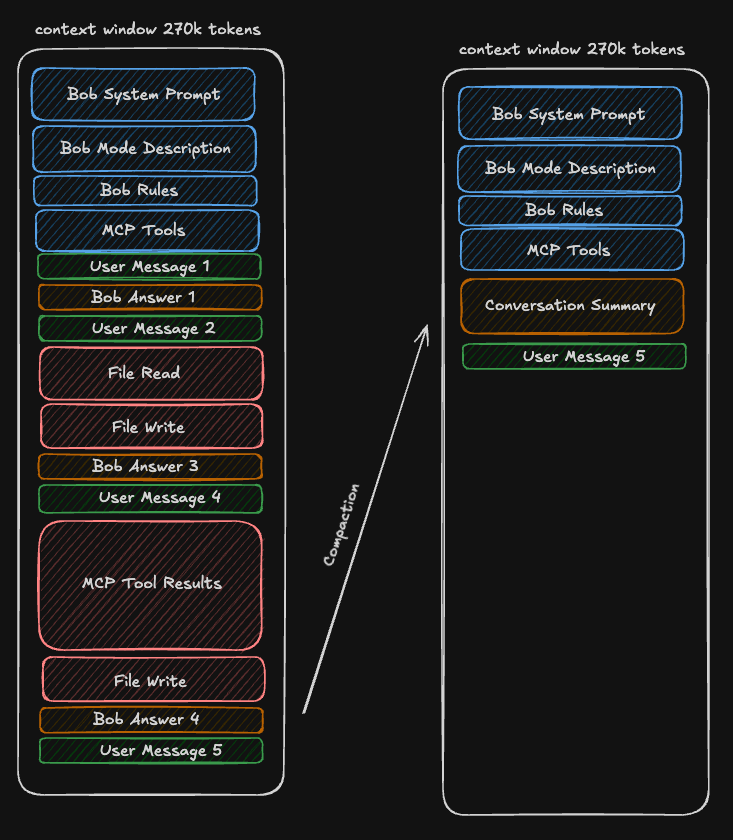
When the window fills up, Bob compacts the conversation. Bob replaces the conversation so far with a summary, and work continues. That keeps the session alive, and it is lossy by design. Bob decides automatically which details survive, and nothing flags the ones that did not. A session that has compacted twice is running on a summary of a summary.
A single MCP call can return tens of thousands of tokens, and a sequence of file reads dilutes what was discussed earlier in the session. Mode descriptions, rules files, and MCP servers do it more slowly and less visibly. Bob breaks the window down by source, and it is worth opening that breakdown again as a setup grows.
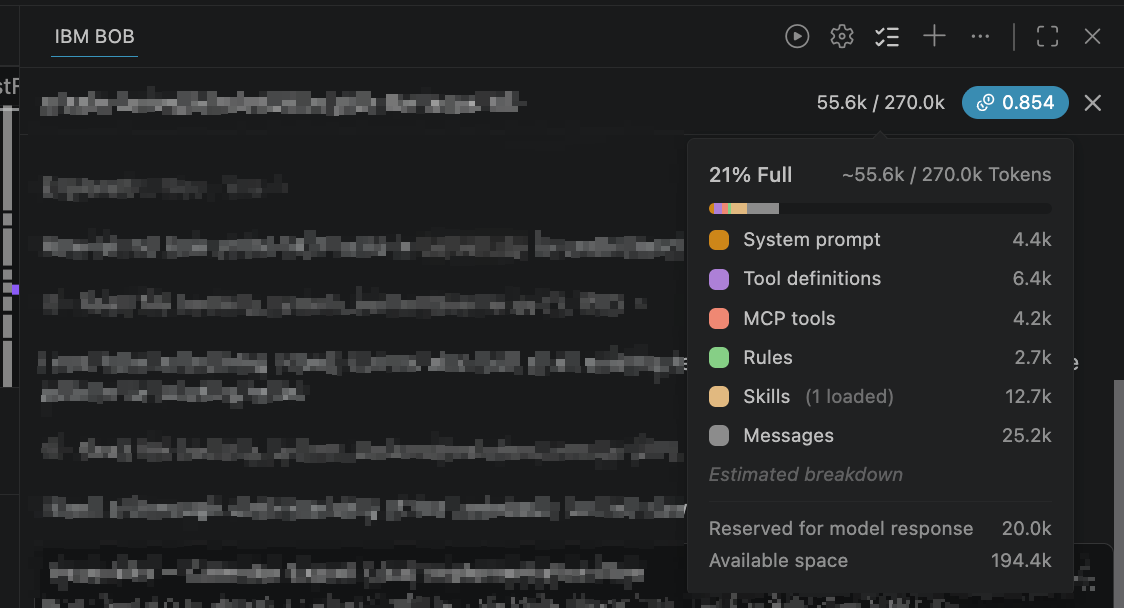
Bobcoins are mainly calculated on a per-token basis. So the cost of a conversation grows quadratically in regard to its length. Longer conversations cost much more Bobcoins than short conversations! (Bobcoins documentation)
Work with the context window instead of against it
- Split work across separate conversations. One task, one session. It is the same reasoning as single responsibility in code. A conversation should have one reason to exist, such as "draw an architecture diagram of component X" or "create an implementation plan for feature Y." Everything in the context window influences what comes next, including the approaches that didn't work. A session that has been stuck tends to stay stuck, because the failed attempts are still there, and the model reads them as evidence about what this task looks like (context poisoning).
- Roll back instead of arguing with Bob. When a conversation drifts into undesired behavior, roll back to the last good message, change the message, and continue from there. This also undoes all the changes that Bob made locally, which keeps the context window small and clean (rollback).
- Keep anything worth keeping in a file, not in the chat. Plans, findings, and decisions belong in a file. A colleague can review a markdown document and hand it to a fresh session; a chat log does neither.
- Subagents keep bulk work out of the context window. Bob decides when to run one, and only the findings come back. Asking for one directly also works, when a task is going to produce output nobody needs to read (subagents).
- Be mindful of what goes into the context window and whether it adds value. Check your guides and sensors regularly, as covered in the following topic, and spend time improving them.
Concept 3: Two kinds of building blocks — guides and sensors
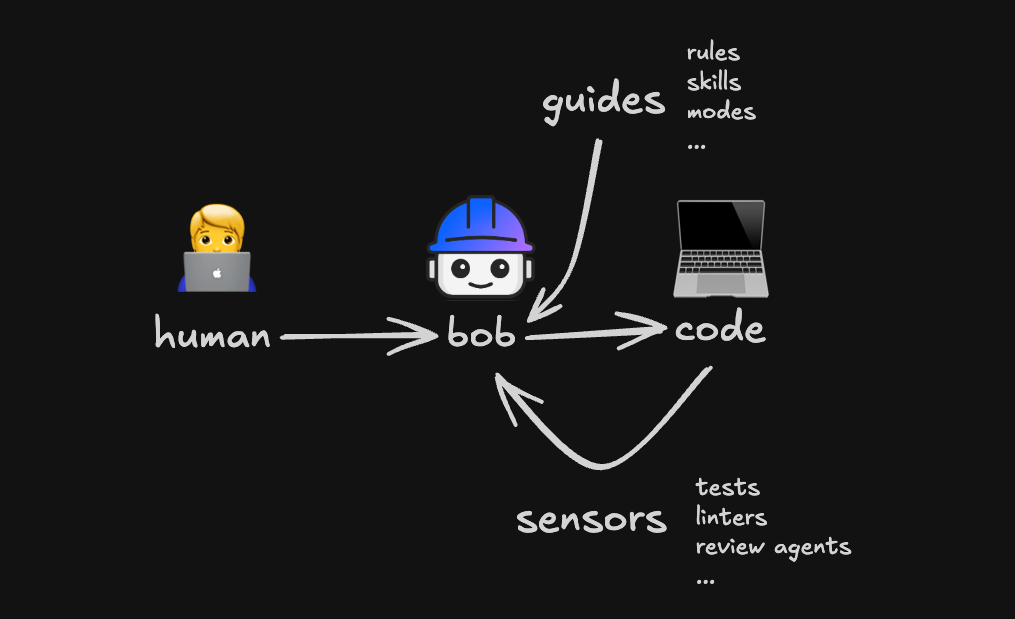
Over a long project, whether the codebase gets better or worse has less to do with Bob than with what shapes its work and checks its output. There are a lot of building blocks available: rules, skills, modes, hooks, subagents, external linters, and review agents. Nearly all of them do one of two jobs.
- Guides steer Bob before or while it works (Feedforward). Rules, skills, and modes are all guides.
- Sensors report back after Bob has acted (Feedback). Tests, linters, type checkers, and interactive browser session and review agents are all sensors.
1. Guides
Anything that is provided to Bob to steer the work is a guide. There are three main building blocks that help you with that, and they work by putting text into the context window additionally to the prompt that you typed. They differ in when that text arrives and what triggers it.
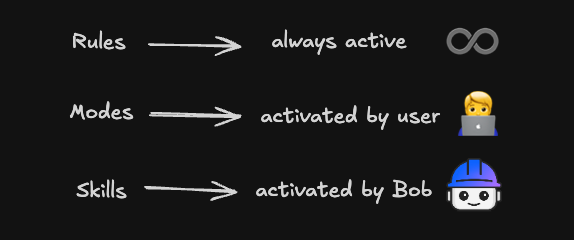
- Rules are always active.
agents.mdat the repo root is the main one, and the main advice about it is to keep it short. Every line competes for attention on every single turn, so a long rules file makes Bob worse at following any individual rule in it (rules). - Modes are user-activated. The integrated modes are: Ask is read-only. Plan works through a planning process and hands the result to Agent, which takes action. Custom modes can be added easily (modes, adding a custom mode).
- Skills Bob activates when it judges them relevant. Only a small skill description is always active. The main body of the skill is only loaded into context on demand. That makes skills very token efficient (skills).
Everything in the rules file uses tokens every turn, whether or not this turn needed it, so keep it minimal and let the rest wait until it applies.
2. Sensors
Anything that gives Bob feedback about the work produced is a sensor. Which signals are useful depends on the codebase and the stack, so the set worth having differs from project to project and takes real work to assemble. The most valuable sensors are machine-runnable and executed by Bob during the implementation phase. Sensors can be split into two different categories.
- Computational sensors are deterministic: tests, linters, type checkers, compilers. Verdicts are exact and repeatable, cheap enough for Bob to run frequently. Coverage is bounded by the systems a team has built and maintains.
- AI-based sensors are flexible and non-deterministic. A review agent reads for intent, and for the things a linter has no rule for. The output is judgement, not measurement. It varies between runs and costs and duration limit how frequently it can be used (code reviews).
Wiring them in has several options, in rough order of friction:
- Hooks are the lowest-friction deterministic option. A check runs at a fixed point, every time, whether or not Bob decided it was relevant. See the hooks documentation.
- Skills are often used as guides, but a skill that runs a review is a sensor, and it is the lowest-friction way to add a non-deterministic check. See the skills documentation.
- Continuous integration (CI) puts a reviewer agent in the pipeline, on every pull request, for the whole team rather than one developer. See the PR review agent in action.
Deep Dive: Run the Cycle
The phase boundaries are also context boundaries, which is the practical reason to keep them distinct: exploration chatter has no business being in the conversation where the code gets written.
1. Explore
Exploration varies widely depending on your role and the task at hand. It can mean onboarding to a new codebase or it can be estimating the blast radius for a major refactoring. Some examples:
- Have Bob produce an architecture diagram of the existing system before changing any of it. See the generating architecture diagrams tutorial, or the same thing on video.
- Ask for a customized getting-started walkthrough from two angles, once as a user moving through the product and once as a developer moving through the code. Providing information about your expertise and task help tailor the document (inspecting a codebase).
- On IBM Z and IBM i, use the platform-specific options. The exploration problem on those systems is different and benefits greatly from the specialized tooling provided in the premium packages. See Premium Package for Z (docs) and the Premium Package for IBM i (docs).
Exploration may also include building things you intend to delete. Implementation is cheap now, so a narrow prototype is the fastest way to find out whether an approach survives contact with the codebase. Kent Beck called this a spike implementation twenty-five years ago, and the discipline is the same: build it to learn something, keep the learning, throw away the code.
Cheap implementation raises the value of architecture and code quality rather than lowering it. It is now easy to produce a large amount of code that works and is wrong.
2. Plan
The planning phase is where the largest leverage is. Everything the plan gets right pays out twice: once in the implementation, and again when the change leaves the author's hands and a colleague has to review it.
What a good plan needs:
- Short and precise, both. Plans need to be read.
- Explicit about the intended outcome, including the uncertain parts. Knowing what is unknown is most of the work, and finding out is the rest.
- In a file. Plans should not live in a chat session.
There are many ways to create a plan, but the integrated Plan mode is the easiest place to start (as in this tutorial).
Plan Mode is built to be agreeable and tends to fill in the gaps. While this enables fast iterations in many cases, more rigor is sometimes necessary. It might build a competent plan around a bad assumption without pushing back on the assumption.
A dedicated skill that argues with the plan — grill-me by Matt Pocock for instance — is the cheapest way to get scrutiny before the assumption becomes code.
On spec-driven development (SDD). The term covers a lot of ground and is still in flux. People treat it as a yes-or-no decision, but it is closer to a spectrum:
- Spec-first: the plan comes before the implementation. This is close to non-negotiable.
- Spec-anchored: the spec stays after implementation, as documentation and as the standard implementations must meet.
- Spec-as-source: the spec is the source file. The human edits the spec; the human does not edit the code.
Which level fits depends on the team, the criticality/maturity of the codebase, and the industry. The overhead coming with the higher levels of SDD can be painful for fast iteration. In automotive, where spec-driven development predates AI by decades, SDD fits existing practice very well.
3. Implement
Implementation is the straightforward phase, and Bob handles almost all of it.
Watching Bob work and interrupting to clarify is optional and often useful. Treat the frequency as a signal: constant interruption means the problem is in the plan, and the fix is to go back rather than to keep correcting.
Do not be reluctant to throw away an entire implementation and return to Plan mode. The code is the cheap part.
4. Verify
Verification falls into two distinct categories: automated verification and manual verification.
Automated verification is driven by the sensors that Bob has available or that are enforced via hooks. They are executed frequently during the implementation phase without human intervention. The main categories with some common examples are:
- Validity: Does it compile, typecheck, parse?
- Measured: pass/fail, type coverage
- Tools:
tsc,mypy,cargo check,javac
- Behaviour: Does it do the right thing?
- Measured: pass rate, branch coverage
- Unit tests, Integration tests, End-to-end tests
- Tools:
pytest,Jest,Playwright,Stryker
- Maintainability: Is this code worth keeping?
- Measured: complexity, duplication, boundary violations
- Tools: ESLint, Ruff, Lizard, ArchUnit
- Security: Is this code safe?
- Measured: findings by severity, CVEs
- Tools: Semgrep, CodeQL, gitleaks,
npm audit
They enable Bob to catch its own mistakes and improve quality during the implementation phase. Good test coverage is essential protection against regressions: it ensures Bob did not break anything.
In this cycle, verification is listed as a separate phase at the end of the loop, which mainly refers to manual verification. Manual verification starts by running the change and comparing observed behavior against the behavior the plan specified. A mismatch mostly narrows to one of two causes:
- The implementation deviated from the plan. The repair is in the code.
- The plan does not reflect what you intended to build. The plan needs to be refined. This is far more common.
Manual inspection therefore tests the plan and the implementation at the same time.
Additional verification should happen in CI/CD pipelines. This is a well-established practice in software engineering, but can be improved by using headless coding agents. One example: an automated review on every pull request, running through Bob Shell, augments human reviewers rather than replacing them. See the video of PR review agent in action and the docs for running Bob Shell non-interactively.
Working in a team
Everything in the preceding sections describes one developer's inner loop. The outer loop starts when the changes move into the review queue. Every diff now arrives faster and with less of its reasoning attached, while the reviewer has more to read and less context in which to read it.
Evidence has to travel with the work. The why matters more than it used to, relative to the how, because the how is no longer the expensive part to produce.
In practice this means the plan travels with the change: teams attach it to the pull request or add it back to the original issue alongside the review. The mechanism depends on the tooling.
What the outer loop does to a team's process is a subject of its own, and a later post.
Some thoughts on prompting
In the past years, there was a large emphasis on prompting LLMs correctly, with a whole job category as "prompt engineer" emerging from it. At this point, a lot of the prompting is handled inside the harness. The importance of specialized prompting techniques has diminished in favor of a methodological approach. These are some guidelines:
- Iterating beats prompting. When Bob does something other than what you asked, roll back and rewrite the message that caused it. Correcting forward leaves the wrong answer, the complaint about it, and the retry all in the window.
- Methodology beats prompting. A prompt is scoped to one session. A rules file, or a check Bob can run itself, keeps working in every session after the one that produced it, which is the only kind of investment here that accumulates.
- Give Bob the brief a senior engineer would get. A competent colleague handed a vague task will ask what counts as done and what they are allowed to touch; Bob will not ask, so put both in the message.
- Say what to do, not what not to do. "Don't use class components" rules out one option and leaves the rest of the space open, so Bob picks from whatever remains, which is another guess. Naming the target instead — function components with hooks — closes it in one turn.
- Any instruction given more than twice belongs in a file. That is what
agents.mdand skills are for. - More detailed prompting instructions can be found in the writing effective prompts tutorial.
Key takeaways
- Absence of structure is the biggest problem. Following the Explore → Plan → Implement → Verify cycle helps you stay focused and achieve your goals faster and more consistently.
- Context is the scarce resource, and phases are context boundaries. Do not carry exploration chatter into implementation.
- The plan is the review artifact. Reviewing a plan beats reviewing a diff, for the author and for the reviewer.
- Anything worth keeping leaves the chat. Plans, decisions, and findings belong in a file. You can diff, review, version, and hand a file to another agent.
- Verification should be machine-runnable, which means you have to design it during planning, not discover it afterward.
Sources and further reading
- Simon Willison, Agentic engineering patterns
- Birgitta Böckeler, Harness engineering
IBM Bob documentation and tutorials:
- Context window management
- Context poisoning
- Bobcoins
- All Bob tutorials
- Starting a project
- Inspecting a codebase
- Generating architecture diagrams
- Creating a plan and implementing complex features
- Writing effective prompts
- Standardizing Bob's behavior
- Adding a custom mode
- Generating secure code with an actor-critic workflow
- Auditing code
- Generating audit reports
- Creating commits and pull requests